
MNIST Dense classification benchmark
Canonical verified digit sources, fixed Dense topology, reproducible initialization and mini batches, held out validation, resource observations, and measured experimental evidence.
This benchmark measures a reproducible Dense classifier on canonical MNIST. It retains the official training and test sources, fixes validation membership, and compares source programming styles under the same native numerical configuration.
The APIs on this page require the current development interpreter with audited Dataset partitions, lazy batches, and mini batch training, together with editor extension 0.1.31. Previously published packages labelled 0.1.0-dev may predate these APIs; that version label alone does not confirm availability.
Verified data and held out roles
Place these decompressed IDX files in a local directory. dataset.mnist(directory, partition) validates file SHA256, exact payload lengths, digit labels, 28 × 28 shape, and the official 60,000/10,000 image counts. It retains compact unsigned byte pixels and scales them by 1/255 when batches materialize. The data are loaded locally; the teaching catalogue remains Iris and Wine.
The checksum verified preparation script downloads the four compressed canonical files from the attributed CVDF mirror, verifies fixed compressed SHA256, decompresses them, and verifies the raw hashes below. Run it from the project directory with bash fetch_mnist.sh; its default destination is build/benchmarks/mnist/data, matching the supplied complete programs. The concise fragment below uses a shorter illustrative mnist path; select the directory actually prepared. No dataset bytes are embedded in the source downloads.
| File | SHA256 |
|---|---|
train-images-idx3-ubyte | ba891046e6505d7aadcbbe25680a0738ad16aec93bde7f9b65e87a2fc25776db |
train-labels-idx1-ubyte | 65a50cbbf4e906d70832878ad85ccda5333a97f0f4c3dd2ef09a8a9eef7101c5 |
t10k-images-idx3-ubyte | 0fa7898d509279e482958e8ce81c8e77db3f2f8254e26661ceb7762c4d494ce7 |
t10k-labels-idx1-ubyte | ff7bcfd416de33731a308c3f266cc351222c34898ecbeaf847f06e48f7ec33f2 |
Retain the canonical MNIST source attribution and its dataset terms. Dataset terms remain separate from Aner software licensing. The distribution includes no inferred writer identifiers.
import aner.dataset

let original = dataset.mnist(directory: "mnist", partition: "train")
let parts = original.partition(validation: 0.1, test: 0.0, seed: 2026, stratify: true, group_aware: false)
let training = parts.train()
let validation = parts.validation()
let testing = dataset.mnist(directory: "mnist", partition: "test")
print(parts.audit())
dataset.require_disjoint(training, testing)
dataset.require_disjoint(validation, testing)
The exact partition is 54,000 training rows and 6,000 validation rows. The official 10,000 test rows support final evaluation. Test data do not select hyperparameters, stopping conditions, or a best epoch. Folds, when used for a different experiment, draw only from the official training source.
Fixed model and training configuration
The measured model has widths 784 → 300 → 100 → 10, ReLU after both hidden Dense layers, and raw output logits. It contains 266,610 trainable scalars. The two hidden widths follow the 300 + 100 fully connected baseline listed on the canonical MNIST page. This experiment uses modern ReLU, cross entropy, and Adam; it does not replicate that historical model or claim its reported error rate. Xavier uniform initialization uses bounds sqrt(6/(inputs + outputs)), Dense seed run seed + layer, and zero biases.
Use five epochs, mini batches of 128, Adam at 0.001, beta1 0.9, beta2 0.999, epsilon 1e-8, and mean one hot cross entropy from logits. Each 54,000 row epoch contains 422 updates; the final batch contains 112 rows. Run seeds are 42, 43, and 44. Epoch shuffle seed is run seed + completedEpoch.
import aner.nn
import aner.ml
import aner.dataset

nn.configure(device: "auto", precision: "Float64", policy: "preserve")
let original = dataset.mnist(directory: "mnist", partition: "train")
let parts = original.partition(validation: 0.1, test: 0.0, seed: 2026, stratify: true, group_aware: false)
let network = nn.mlp(inputs: 784, hidden: List(300, 100), outputs: 10, seed: 42)
let model = ml.classifier(network, standardize: false, optimizer: "adam")
let config = ml.training(epochs: 5, batch: 128, rate: 0.001, seed: 42)
    .validation(parts.validation()).select_best(false)
let fitted = model.fit(parts.train(), config: config, progress: true)
let testing = dataset.mnist(directory: "mnist", partition: "test")
print(fitted.evaluate(testing).summary())
The preserve profile retains Float64 on CPU or CUDA. CPU Float32 uses Float32 stored values and matrix products, with Float64 intermediates in some checked scalar and reduction operations; it does not imply exclusively Float32 arithmetic. CUDA uses native Float64 or strict Float32 without TF32, and Metal/MPS uses native Float32. nn.execution() distinguishes storage, computation, and accumulation precision. Metal/MPS resolves a Float64 preserve request to CPU with a warning. Select adapt to permit MPS Float32, or explicitly select Float32 for matched precision comparisons. Command line device and precision policy options can change the run configuration while keeping the source program the same. Tensor devices documents this contract.
Concise, functional, and class based source
A concise program delegates fixed epoch mini batches to ml.training. The supplied functional program exposes each Dense initialization and activation in build_network, then composes a train_network function around the immutable training contract and classifier fit. The class based program exposes parameter tensors, forward and detached inference methods, a replaceable objective function, explicit batch loops, and keyed optimizer updates while preserving the same numerical operation sequence. Each style uses the same batch schedule and immutable source identity.
Download the complete concise program, functional program, and class based program. Corresponding Jupyter concise, functional, and class based notebooks, and VS Code concise, functional, and class based notebooks preserve the source workflow. Source programs expect the repository root as their working directory. Notebook data cells use a local mnist directory: run the preparation script as bash fetch_mnist.sh mnist from the notebook directory. Downloaded notebooks contain no saved results.
The custom programs retain Dataset views and explicitly check training roles and disjoint membership before materializing Tensors. Those checks are essential because a materialized Tensor does not retain its Dataset role. The configured mini batch classifier enforces its retained fitting and selection history automatically.
nn.optimizer("adam", rate) retains resident moments and a separate update counter for each stable parameter key. Retain each returned replacement parameter. Distinct trainable tensors require distinct keys; changing shape, device, or dtype under an existing key raises an error. reset() deliberately discards that optimizer history.
Custom objectives belong in an explicit Tensor forward/training loop, as exposed by the class based example. The classifier's built in objective remains cross entropy or its documented probability MSE.
Measured loss and progress
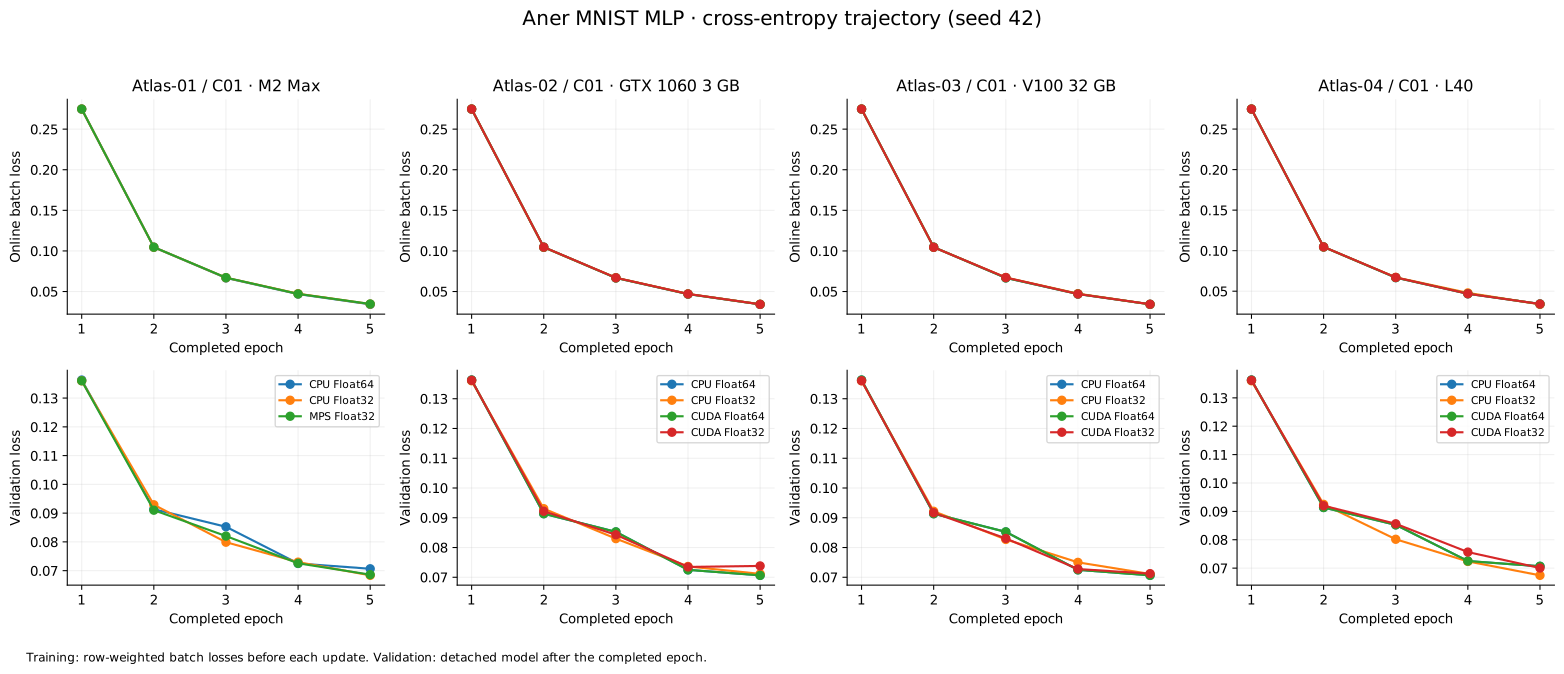
Online training loss is the row weighted mean of batch losses measured before their updates. It combines observations from changing parameter states across the epoch. Validation loss and accuracy are detached passes over the held out validation rows after the epoch. The final training metric is a separate pass over the returned parameter snapshot. These phases must be labelled separately.
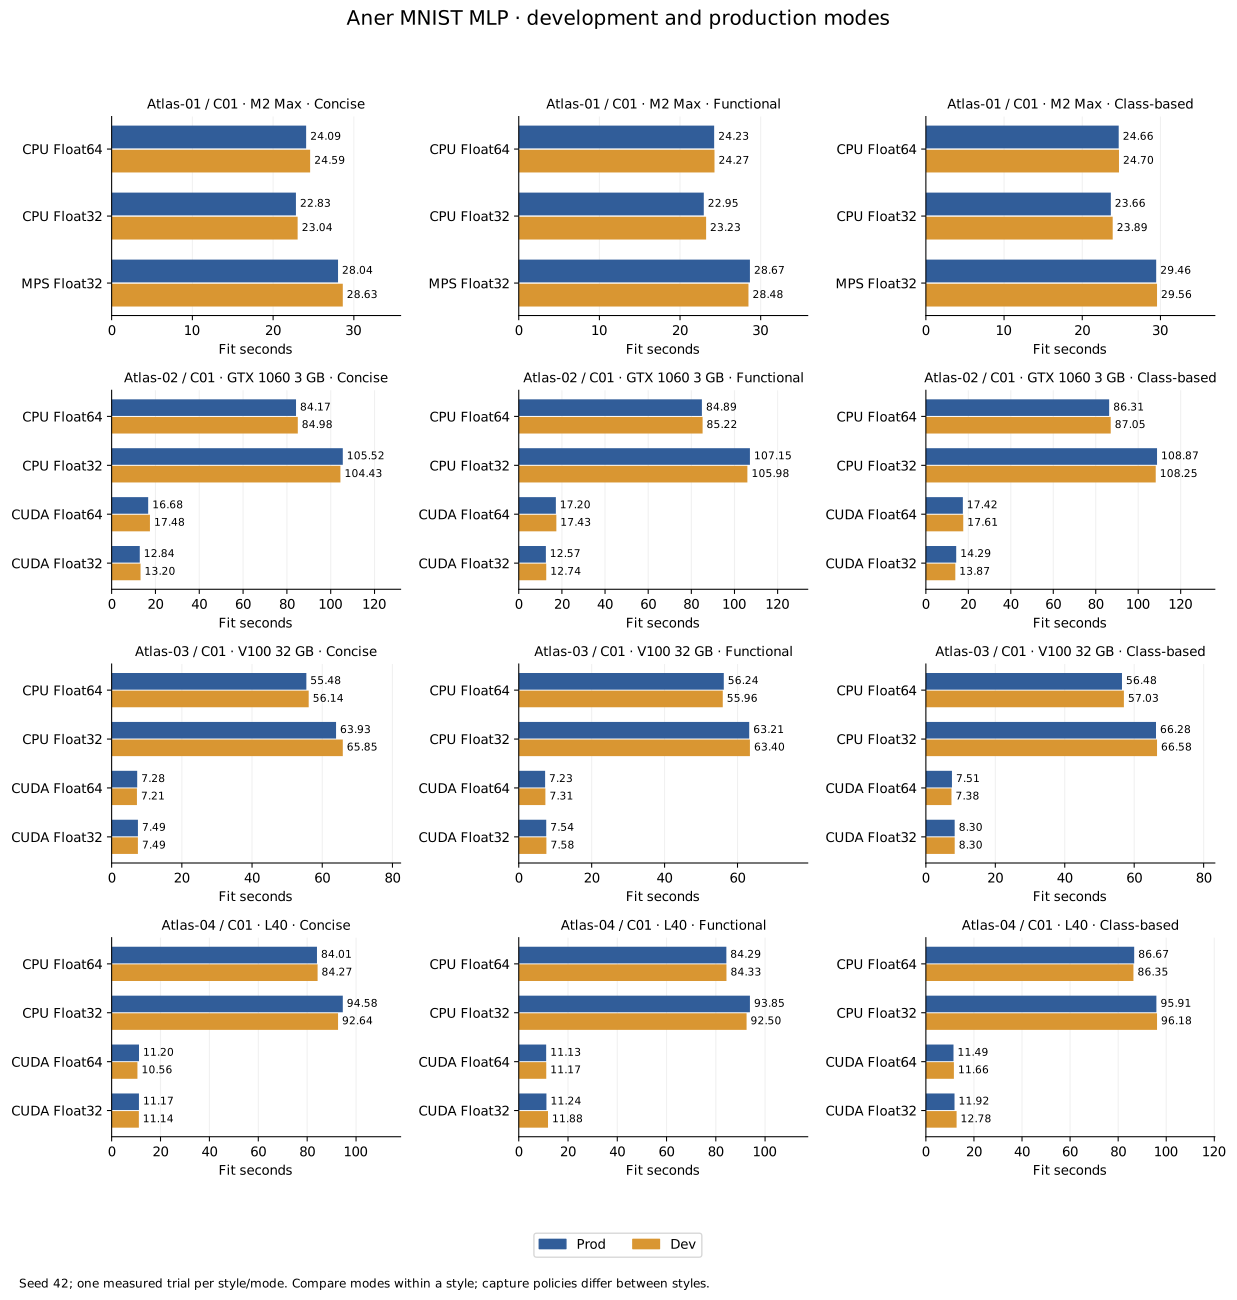
Development mode records bounded epoch observations and separate training/validation curves. Disable automatic variable capture with dev.automatic(false) for larger experiments and keep explicit captures or progress observations that answer a research question. Production mode removes those automatic observations; numerical precision and the optimization algorithm remain independently configured. The supplied pipeline captures its first batch at selected epochs and performs an additional final backward pass for gradient inspection; the explicit class loop captures its last batch each epoch. Compare Dev against Prod within the same source style. These observations differ between styles, so their timing difference does not isolate a common instrumentation cost.
For this fixed epoch budget, the configured classifier’s CLI progress estimates remaining update loop time after two completed mini batch epochs from the mean measured epoch duration. It excludes future final evaluation and report generation, and can change with hardware contention or capture cost. It is not an estimate of convergence.
Notebook cells default to a 120 second execution timeout. Before a larger Jupyter training cell, run %aner timeout 600 in a separate cell. In VS Code set aner.notebook.timeoutMs to 600000. These changes affect subsequent cells and retain current variables; timeout or cancellation terminates the session and clears its variables. Increase the limit to match the planned run rather than treating it as an estimate of training completion.
Reproducibility and resource reporting
The native manifest exporter retains verified source file hashes, exact ordered split row IDs, all epoch permutations, class counts, and initial parameter bytes. Index artifacts use UInt32 little endian; initial parameters use Float64 little endian with named shapes and file SHA256. Both precisions start from those same canonical parameters. Pixel normalization occurs in CPU Float64, followed by the declared placement/precision conversion.
Report each trial's actual device, precision, provider, compiler/build, CPU threading policy, fixed seeds, epoch losses, validation/test results, training duration, and measured resource usage. Device timing requires completion synchronization. Keep initialization, source loading, training, validation, final test evaluation, and report generation distinguishable. This experiment fixes a two thread CPU provider policy for comparison; it is not a test of maximum CPU throughput across every available core. Different batch sizes or thread counts are separate experiments.
Native Tensor counters measure owned host and accelerator buffers, including observed peaks. The supplied programs reset these counters before model construction and snapshot them after final test evaluation, before the final explicit model capture. They omit dataset storage, graph metadata, vendor workspaces, and unrelated process allocations. Whole process resident memory and accelerator allocator observations require separate measurements. Process RSS is the operating system lifetime high water mark for a fresh interpreter process; it includes dataset loading, fitting, final test evaluation, and any report preparation. CUDA process allocation is sampled from the driver every 100 ms and includes context and provider workspaces; brief peaks can be missed. Neither measurement isolates training only storage. Float32 datatype width does not imply that total process memory halves; the current CPU implementation also keeps numerical host caches.
Repeat the fixed seeds and report individual results plus aggregate variation. A single small demonstration or a single best run does not establish general throughput or accuracy. Matched precision comparisons and explicit convergence checks provide different evidence from comparisons that change precision.
Platform identifiers and configuration revisions
Public reports identify test platforms by stable aliases such as Atlas-01. The number is an inventory identifier; it does not encode location, operating system, processor generation, performance class or memory capacity. Real machine names and connection details belong to a separate internal registry.
Each result also cites an immutable configuration revision, such as Atlas-02 / C01. CPU, GPU, allocated/visible memory, operating system, driver, numerical provider, build and threading policy are recorded with that revision. A material change, including an increase or decrease in VM RAM, keeps the platform alias and creates the next revision. Earlier measurements retain their original configuration and memory values. The inventory distinguishes installed unified RAM, guest visible OS memory and driver reported GPU memory.
A different physical computer or VM receives a new alias, including two systems with the same processor generation but different chip variants. A hostname or connection address change does not change the alias. Precision, seed, source style, Dev/Prod mode, topology, batch size and epoch budget remain explicit experiment settings.
This experiment uses C01 for all four platforms. Downloads associate every trial and aggregate with configuration_id, configuration_revision and the platform alias. Statistics are grouped by configuration, device and precision; different revisions are never pooled. No C02 measurements are implied by these naming examples.
Measured hardware and execution conditions
Measurements were collected on October 11 to 12, 2026. Atlas-01 uses an Apple M2 Max with 12 logical CPU cores, 38 integrated GPU cores, and 64 GiB unified RAM, running macOS 26.7.1 (build 25G241). Its C++20 Release interpreter used Apple Clang 21.0.0 and Apple Accelerate. VECLIB_MAXIMUM_THREADS=2 requested a provider thread cap; the actual Accelerate worker count was unavailable.
Atlas-02 is a KVM guest with two vCPUs on a Xeon E5 to 2697 v2 and a GeForce GTX 1060 with 3 GiB dedicated memory. Atlas-03 is a KVM guest with 24 vCPUs on a Xeon Gold 6248 and a Tesla V100 PCIe with 32 GiB dedicated memory. Both guests run Ubuntu 26.04.1 with kernel 7.0.0-38 and driver 580.178.04. Guest visible OS memory is approximately 15.05 GiB and 60.47 GiB respectively. Both use OpenBLAS 0.3.32 with two queried worker threads, selecting Sandybridge and SkylakeX kernels respectively.
The same Linux Release binary was compiled on Atlas-02 using GCC 13.4.0 and CUDA 12.4.131, with native code for compute capabilities 6.1 and 7.0, then executed unchanged on Atlas-03.
Atlas-04 is an Ubuntu 22.04.5 guest with kernel 5.15.0-198, glibc 2.35, 32 guest vCPUs reporting a Xeon E5 to 2630 v3, and approximately 125.78 GiB guest visible RAM. Its NVIDIA L40 reports compute capability 8.9 and 46,068 MiB total device memory; the driver is 615.71.09.
A fresh Release interpreter was compiled on Atlas-04 using GCC 11.4.0 and the same CUDA 12.4.131 compiler, targeting native sm_89. Its private OpenBLAS 0.3.32 source build selects Haswell kernels and reports two worker threads. That build omits Fortran and LAPACK; the measured CPU products use SGEMM/DGEMM.
The 125 original source files shared with the earlier Linux source packet are byte identical; generated headers were produced afresh by CMake. The source archive and resulting binary have separately recorded fingerprints. The operating system, compiler, provider build and driver differ from the other guests, so the timings compare complete host configurations rather than isolating the graphics card alone. All builds use -O3 -DNDEBUG, -fno-fast-math, and -ffp-contract=off; CUDA source also uses --fmad=false. CUDA matrix products use native Float64 or strict Float32 without TF32. See the verified hardware and build record for exact fingerprints and provider details.
Existing services remained running. The V100 had one other resident GPU context using approximately 2,282 MiB before the experiment; this is separate from the benchmark process allocation reported below. Resident allocation does not prove active compute contention. A separate 1 Hz environment monitor started during the Linux CPU Float64 profiles, before CUDA measurements. No other compute context was present in the Atlas-04 preparation snapshot. Its additional GPU environment monitor started before the first native profile, with a nominal one second interval, and continued through subsequent private measurements. The VM was not reserved exclusively; a snapshot does not establish absence of contention throughout the experiment. These are shared machine observations, not exclusive hardware laboratory results. Compilation and additional training experiments did not overlap native measured runs on the same host.
Measured training results
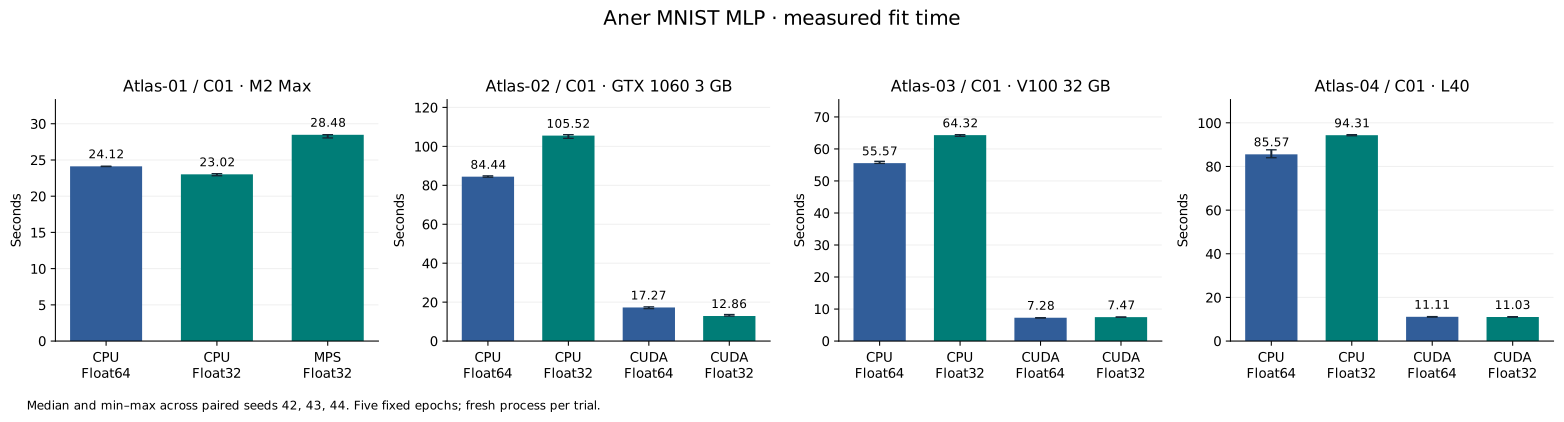
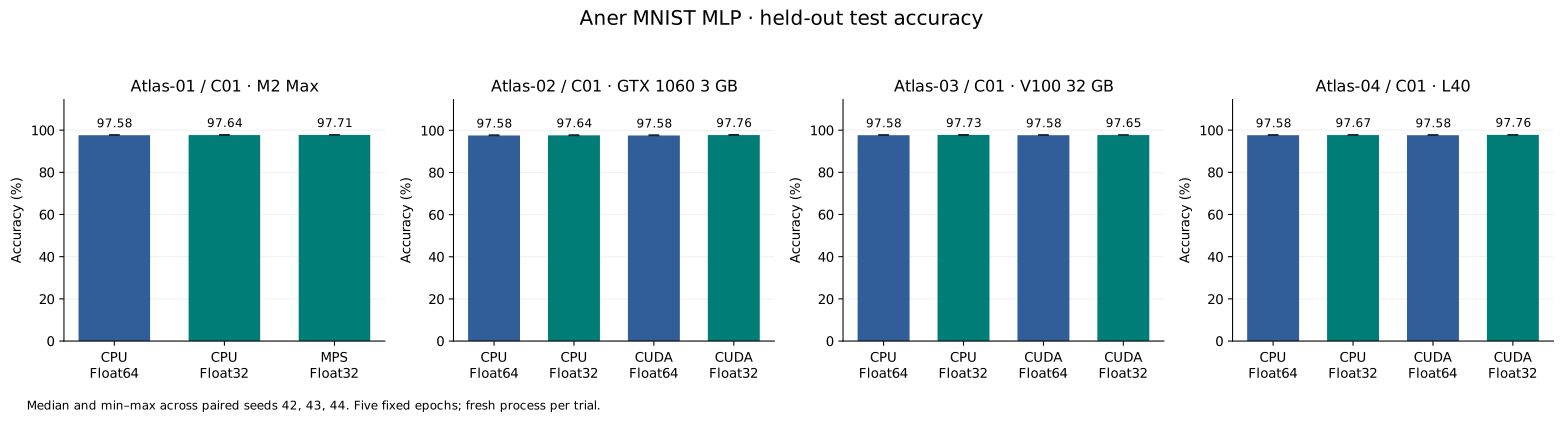
The following results use the concise program in production mode, the fixed fifth epoch, and paired seeds 42, 43, and 44. Each table entry is the median of three runs. Dataset loading is excluded from fit_seconds; fitting includes model setup, training, epoch validation, final training metrics, and parameter detachment. Test evaluation is measured separately. RSS and sampled CUDA process allocation cover the process lifetime. Missing MPS process allocation is not represented as zero.
| Platform / configuration | Actual placement and precision | Fit time, seconds | Official test accuracy | Peak process RSS, MiB | Sampled CUDA process memory, MiB |
|---|---|---|---|---|---|
Atlas-01 / C01 | CPU Float64 | 24.124 | 97.58% | 173.609 | Unavailable / not applicable |
Atlas-01 / C01 | CPU Float32 | 23.015 | 97.64% | 193.484 | Unavailable / not applicable |
Atlas-01 / C01 | Metal/MPS Float32 | 28.478 | 97.71% | 144.234 | Unavailable / not applicable |
Atlas-02 / C01 | CPU Float64 | 84.440 | 97.58% | 201.285 | Unavailable / not applicable |
Atlas-02 / C01 | CPU Float32 | 105.518 | 97.64% | 204.164 | Unavailable / not applicable |
Atlas-02 / C01 | CUDA Float64 | 17.266 | 97.58% | 310.824 | 92.000 |
Atlas-02 / C01 | CUDA Float32 | 12.855 | 97.76% | 307.602 | 82.000 |
Atlas-03 / C01 | CPU Float64 | 55.572 | 97.58% | 201.125 | Unavailable / not applicable |
Atlas-03 / C01 | CPU Float32 | 64.315 | 97.73% | 204.262 | Unavailable / not applicable |
Atlas-03 / C01 | CUDA Float64 | 7.281 | 97.58% | 338.176 | 340.000 |
Atlas-03 / C01 | CUDA Float32 | 7.469 | 97.65% | 342.746 | 330.000 |
Atlas-04 / C01 | CPU Float64 | 85.567 | 97.58% | 200.172 | Unavailable / not applicable |
Atlas-04 / C01 | CPU Float32 | 94.315 | 97.67% | 202.027 | Unavailable / not applicable |
Atlas-04 / C01 | CUDA Float64 | 11.112 | 97.58% | 404.941 | 458.000 |
Atlas-04 / C01 | CUDA Float32 | 11.032 | 97.76% | 465.691 | 448.000 |
CUDA Float64 was approximately 4.89 times faster than matched CPU Float64 on Atlas-02 and 7.63 times faster on Atlas-03. On Atlas-04, CUDA Float64 was approximately 7.70 times faster than matched CPU Float64. Native CUDA Float32 fit took 11.032 seconds, compared with 11.112 seconds for Float64; the observed three seed ranges overlap. These ratios apply to the stated workload and two thread CPU policy. They do not compare accelerator peak arithmetic or all core CPU throughput.
Lower precision did not guarantee lower training time: CPU Float32 was slower than CPU Float64 on all three Ubuntu guests, and V100 Float32 was slightly slower than V100 Float64. On Atlas-01, Metal/MPS Float32 took longer than CPU Float32. Dispatch, synchronization, transfer, conversion, host checks, provider behavior, and workload dimensions can affect elapsed time; these measurements do not assign a measured cost to each factor. The observed accuracy variation across three seeds does not establish one precision as generally more accurate. Native Metal/MPS Float64 remains unavailable; the preserve policy executes that request as CPU Float64 with a warning.
Measured memory
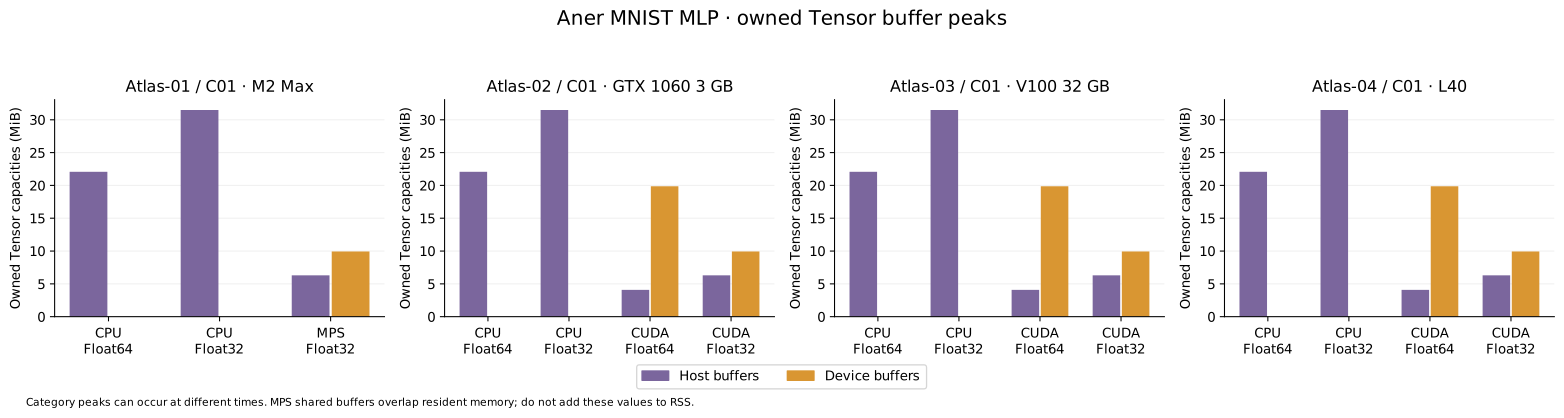
The current CPU Float32 implementation owns both Float32 matrix caches and a Double payload for checked native operations, with Float64 host gradients. Its memory does not halve when Float32 is selected. CUDA native Float32 buffers occupy fewer bytes than Float64 buffers, but context and provider workspaces dominate the sampled process allocation in this workload. Native Tensor counters, OS RSS, and driver process allocation have different scopes.
On Apple unified memory, host/device buffer categories do not represent physically independent memory pools. Individual category peaks can occur at different times. Do not add these peaks together or add device allocation to RSS to infer a process peak.
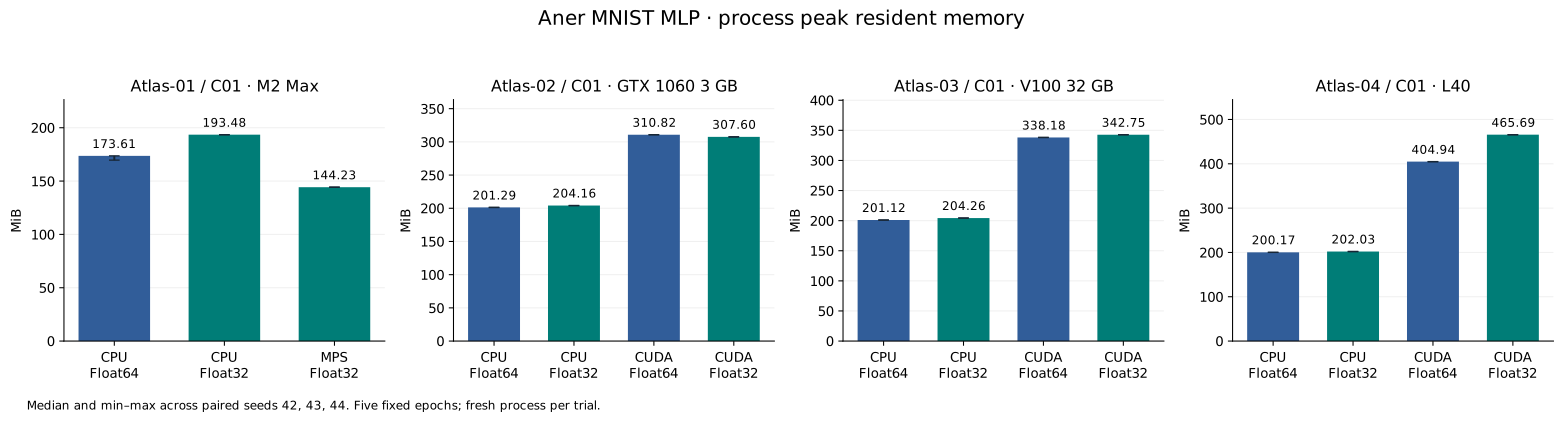
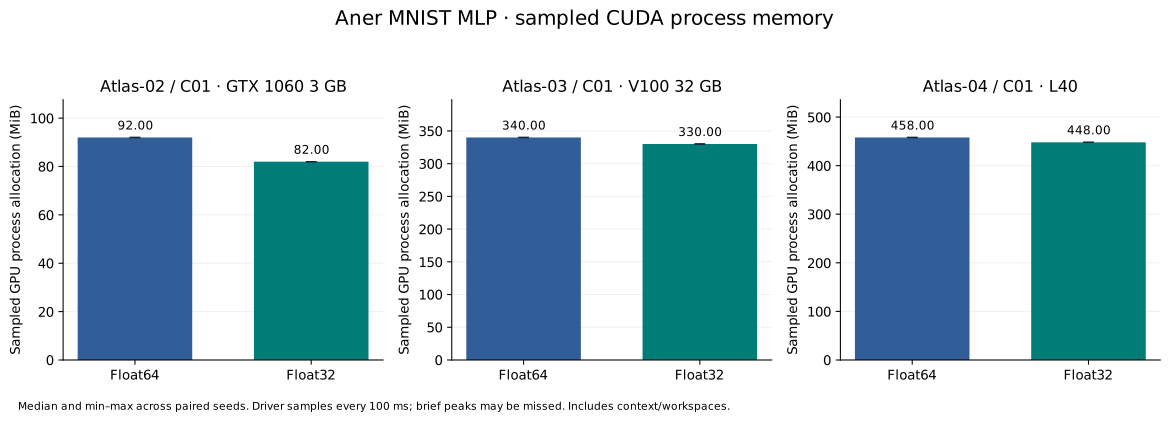
Measured source styles and runtime modes
All 120 native trials passed: eight cases per profile across 15 profiles. The concise production path uses three paired seeds; each profile also includes concise Dev, functional Prod/Dev, and class based Prod/Dev runs at seed 42. Within every profile, the six seed 42 style/mode cases produced identical final train/test metrics and all five epoch curves. Development reports each retained five progress observations without dropped captures.
The following single seed chart compares modes within each source style. It is not a repeated timing estimate of instrumentation overhead. Pipeline and class based capture policies differ, and the pipeline also prepares detached checkpoint ready Adam state. Small timing reversals between Dev and Prod are compatible with normal system activity and measurement variation; no fixed speedup is promised.
Download the individual public trials and three seed production aggregates. The public trial record includes source/binary fingerprints, epoch metrics, timing, native owned buffer peaks, process RSS, and available sampled CUDA process memory. Reproduce each configuration before extending a conclusion to another workload. The independent protocol manifests generated on all three Ubuntu hosts were byte identical to the Atlas-01 manifest; cross provider floating point bitwise identity is not promised.
Complexity
Let n be training rows, v validation rows, b batch size, e epochs, p parameter count, and a the per row activation width summed across layers including the input width. Dense numerical work is O(e(n + v)p + e ceil(n/b)p). Inference over t test rows adds O(tp). Working numerical storage is O(ba + p), with two additional O(p) Adam moment buffers. The compact source retains O((n + v + t) × 784) bytes; schedules and partition membership retain O(n + v + t) indices. A fresh fit also sorts provenance membership in O((n + v) log(n + v)); epoch schedule construction and hashing add O(en). If q Tensor operations per training batch retain a graph with G nodes, admission adds expected O(e ceil(n/b) qG) traversal work. The fitted result retains O(e) epoch metrics and schedule fingerprints; the 64 event Dev capture limit does not bound that history. Provider workspaces and report observations add separate costs.
Dataset partitions defines exact membership, group/fold constraints, workload bounds, and preprocessing complexity. Neural workflows defines fitted state and checkpoint continuation.